n8n Worker Concurrency: A Repeatable Tuning and Rollback Guide
Compare n8n worker concurrency settings under a controlled webhook workload, measure queue and dependency pressure, and define acceptance and rollback criteria.
Checked against the cited sources on .
What does n8n worker concurrency control?
n8n worker concurrency controls how many jobs a queue-mode worker can process simultaneously. For teams operating an existing self-hosted deployment, the useful question is which setting meets their workload requirements while keeping queues, resources and dependencies within agreed limits. This guide proposes a repeatable operating experiment for answering that question.
n8n documents a default worker concurrency of 10 and recommends 5 or higher. Those values are configuration guidance, not evidence of an optimal setting for your workflows. Parallel jobs and request rate are different quantities: a worker setting does not specify how many API requests your workflows will make over time.
The method below compares configurations against the same offered workload, separates response behavior from business completion, and preserves a configuration to restore. It assumes queue mode already works; installation, monitoring-stack deployment and platform-specific deployment commands are outside its scope.
In our view, a concurrency experiment is worth doing only when another operator can explain and repeat it. Clear measurement boundaries matter as much as the setting being compared.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/scaling/enable-queue-mode.md at main · n8n-io/n8n-docs · GitHub, n8n-docs/docs/deploy/host-n8n/configure-n8n/scaling/control-concurrency.md at main · n8n-io/n8n-docs · GitHub, API load testing
Which setting actually determines worker concurrency?
For self-hosted n8n queue mode, N8N_CONCURRENCY_PRODUCTION_LIMIT supplies the worker concurrency when its value differs from -1. Otherwise, n8n falls back to the --concurrency flag or its default. Do not treat the environment variable as an additional fleet-wide ceiling layered over each worker's flag.
Before changing anything, record the installed n8n version, worker count, startup command, environment override and resource limits. Preserve the last acceptable configuration as a complete deployment revision. A record containing only the flag can miss the environment value that actually determines concurrency.
The inspected master-branch implementation logs resolved concurrency during worker startup. That evidence comes from mutable master without a release identifier, so match the implementation to your installed release before relying on its output. The same release-matching limitation applies to the implementation and schema observations used later in this guide.
As editorial practice, verify each worker after deployment and retain the relevant startup output with the run record. If your release does not expose equivalent output, establish another release-appropriate verification method before interpreting a comparison.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/scaling/enable-queue-mode.md at main · n8n-io/n8n-docs · GitHub, n8n-docs/docs/deploy/host-n8n/configure-n8n/scaling/control-concurrency.md at main · n8n-io/n8n-docs · GitHub, n8n/packages/cli/src/commands/worker.ts at master · n8n-io/n8n · GitHub
Which prerequisites should already be working?
n8n documents that queue-mode workers need access to Redis and the n8n database, and that their encryption keys must match the main instance's key. Establish those prerequisites before treating a stalled execution as a concurrency problem.
For this experiment, use a deployment that already completes representative executions. As suggested preparation, retain one known working request and its expected business result, confirm access to operational observations, and identify who can stop the test and restore the previous configuration.
Sources: Enable queue mode | Deploy | n8n Docs
How do you build a repeatable comparison workload?
Use a representative production-webhook workload with controlled inputs and a fixed arrival schedule. Grafana's k6 documentation describes constant-arrival-rate scenarios as starting iterations at a constant rate, which supports this comparison design. An iteration can contain multiple requests, so record iteration rate and request count separately.
Define the webhook's response contract before writing assertions. Grafana recommends response checks and performance thresholds, but an accepted webhook request may not establish business completion. Decide what observable result proves that the workflow performed its intended work.
As a suggested workload design, prepare a repeatable payload set covering the important request shapes, plus an expected result for each case. Use an isolated destination or another locally approved approach for writes, and specify how test records will be identified and reconciled.
Sources: Scenarios, API load testing
What should stay constant between candidates?
Change n8n worker concurrency alone in the initial comparison. Alex Cinovoj's 2026 vendor operating guide recommends testing a sizing change against the same workload; it supplies operating advice rather than a controlled comparative result. The experiment record below is our suggested way to make that advice reviewable.
Complete this record before the baseline.
| Control | Record and hold constant |
|---|---|
| Workflow | Revision and relevant configuration |
| Payloads | Cases, proportions and expected results |
| Workers | Count and resource limits |
| Dependencies | Environment and test destinations |
| Requests | Arrival schedule and requests per iteration |
| Retries | Attempts, pauses and batching |
| Observation | Load duration and recovery window |
| Preparation | Initial queue and dependency conditions |
Sources: Self-Hosting n8n at Scale, A Real Runbook | Alex Cinovoj
How do you verify that the intended load actually arrived?
Inspect the generator before attributing an outcome to n8n. Grafana defines k6 dropped_iterations as iterations that did not start because arrival-rate executors lacked virtual users, or because iteration-based executors ran out of allowed time. This is a load-generator signal.
As an editorial decision rule, mark a run inconclusive when the intended arrival schedule was not delivered closely enough for the planned comparison. Retain scheduled iterations, started iterations, actual requests and dropped iterations, and compare them with ingress observations where available.
k6 supports scenario-specific environment variables and metric tags. Use them to identify candidate runs and payload groups, while remembering that a tag does not prove equivalent environments. Suggested identifiers include a run name and workflow revision; keep their interpretation consistent across records.
Sources: Scenarios, Built-in metrics
What should you measure during each run?
For n8n worker concurrency comparisons, combine queue observations with execution outcomes, container resources and dependency evidence. n8n exposes waiting and active job counts, plus completed and failed job counters across workers. Completed and failed counters run from instance startup, so compare interval changes and account for restarts.
The following is a suggested measurement contract, not a native n8n report.
| Dimension | Observation | Interpretation boundary |
|---|---|---|
| Correctness | Expected business result | Not established by completion counts |
| HTTP | Response checks and latency | Depends on response contract |
| Queue | Waiting and active jobs | Counts are not per-job delay |
| Completion | Completed and failed deltas | Account for restarts |
| Resources | CPU and memory over time | Not isolated to one workflow |
| Dependencies | API errors and database activity | Correlate before diagnosing |
Capture both the load period and recovery after arrivals stop.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/basic-configuration/configuration-examples/enable-prometheus-metrics.md at main · n8n-io/n8n-docs · GitHub, Enable Prometheus metrics | Deploy | n8n Docs, Runtime metrics, API load testing
How do you separate queue waiting, worker processing and HTTP response time?
Use custom instrumentation if you need execution-level timing. As an editorial method, attach a correlation identifier and ingress timestamp to each test request, associate that identifier with its execution, and correlate timestamped worker-start and worker-finish observations. Use a consistent clock basis across components and report unmatched observations.
The inspected master-branch worker implementation emits start and finish messages containing execution and job identifiers. Its start message occurs after initial execution-data retrieval. Therefore, call ingress-to-start elapsed time dispatch-to-start delay: it includes dispatch and preflight overhead and is not exact Redis queue residence time.
Treat start-to-finish log elapsed time as a worker-processing proxy, not a universal execution-duration metric. Measure HTTP response time separately at the generator. The generated execution schema includes createdAt, startedAt and stoppedAt, but field presence alone does not establish semantics or a supported queue-delay calculation.
The cited documentation does not document a native per-execution queue-delay histogram. If correlation coverage or clock consistency is inadequate, retain the measurements you can defend and mark the affected timing comparison inconclusive.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/basic-configuration/configuration-examples/enable-prometheus-metrics.md at main · n8n-io/n8n-docs · GitHub, n8n/packages/cli/src/scaling/job-processor.ts at master · n8n-io/n8n · GitHub, n8n/docs/generated/postgres-schema/public.execution_data.md at master · n8n-io/n8n · GitHub
How do you collect queue and resource signals safely?
For self-hosted n8n, enable metrics with N8N_METRICS=true and queue metrics with N8N_METRICS_INCLUDE_QUEUE_METRICS=true. n8n exposes queue metrics on main instances and instructs operators to expose the metrics endpoint only to internal services consuming Prometheus data.
For containerized deployments, Docker documents docker stats as a source of CPU, memory usage, memory limit and network I/O observations. Keep the collection method consistent: on Linux, the Docker CLI subtracts cache from memory usage, while the API reports total memory and cache separately.
As suggested collection practice, align queue and resource observations on the run timeline and preserve instance restart information. Container observations do not identify which dependency caused a slowdown.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/basic-configuration/configuration-examples/enable-prometheus-metrics.md at main · n8n-io/n8n-docs · GitHub, Enable Prometheus metrics | Deploy | n8n Docs, Runtime metrics, docker container stats
How do you identify dependency pressure before increasing concurrency?
Inspect external-service errors and database observations alongside queue behavior. n8n documents service rate-limit responses and cautions that excessive PostgreSQL connections may degrade performance. A growing queue is a reason to investigate these signals before choosing a higher setting.
As editorial diagnostic advice, compare when queue growth begins with changes in API errors, database activity and resource use. Look for repeated patterns across comparable runs rather than assigning a cause from one coincident spike.
We think a concurrency increase that merely shifts pressure into a dependency is a poor operating trade. The decision should reward acceptable end-to-end behavior, including recovery, rather than a shorter queue at one moment.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/basic-configuration/use-environment-variables/database.md at main · n8n-io/n8n-docs · GitHub, PostgreSQL: Documentation: 18: 27.2. The Cumulative Statistics System, PostgreSQL: Documentation: 18: 27.3. Viewing Locks, n8n-docs/docs/integrations/builtin/handle-rate-limits.md at main · n8n-io/n8n-docs · GitHub
What should you do when downstream requests are rate-limited?
n8n identifies HTTP 429 in node errors as a service rate-limit response. Inspect those errors and obtain applicable quotas from your provider's own documentation.
n8n documents Retry On Fail as adding a pause between attempts, and Loop Over Items with Wait as a way to batch and pause requests. These controls do not establish a coordinated rate limit across all workers.
If the evidence suggests changing retries or batching, create a separate retry-policy experiment with its own baseline. Otherwise, any observed difference would combine a concurrency change with a changed request pattern.
Sources: n8n-docs/docs/integrations/builtin/handle-rate-limits.md at main · n8n-io/n8n-docs · GitHub
What should you inspect when PostgreSQL becomes the constraint?
For self-hosted n8n PostgreSQL connections, DB_POSTGRESDB_POOL_SIZE controls parallel open connections. n8n warns that excessive connections may degrade performance; the documentation does not supply a workload-specific sizing formula.
PostgreSQL 18 documents pg_stat_activity for observing current server-process activity, including state and query, and pg_locks for examining outstanding locks and investigating contention. Use those observations to investigate the database during the same run window as queue measurements.
PostgreSQL 18 observation has boundaries: cumulative statistics can lag or remain cached within a transaction, and visibility into other sessions depends on privileges. Outstanding locks alone do not prove that concurrency caused a regression. As editorial advice, involve the database owner in interpreting activity and contention before changing the pool.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/basic-configuration/use-environment-variables/database.md at main · n8n-io/n8n-docs · GitHub, PostgreSQL: Documentation: 18: 27.2. The Cumulative Statistics System, PostgreSQL: Documentation: 18: 27.3. Viewing Locks
How do you compare candidates and define acceptance criteria?
Define acceptance criteria before running candidates. Grafana's k6 guidance recommends pass/fail criteria tied to service-level objectives or other important metrics. Your team must supply the workload requirement, latency targets, recovery allowance and resource budgets; this guide proposes no universal thresholds.
Use the blank results table below as an editorial comparison template. Enter observations rather than an overall impression, and retain underlying time series where a summary could hide growing backlog or a brief resource peak.
| Observation | Baseline | Candidate A | Candidate B |
|---|---|---|---|
| Effective concurrency per worker | Not recorded | Not recorded | Not recorded |
| Delivered load | Not recorded | Not recorded | Not recorded |
| Successful business outcomes | Not recorded | Not recorded | Not recorded |
| HTTP response latency | Not recorded | Not recorded | Not recorded |
| Dispatch-to-start delay | Not recorded | Not recorded | Not recorded |
| Worker elapsed-time proxy | Not recorded | Not recorded | Not recorded |
| Queue recovery | Not recorded | Not recorded | Not recorded |
| CPU | Not recorded | Not recorded | Not recorded |
| Memory | Not recorded | Not recorded | Not recorded |
| Downstream errors | Not recorded | Not recorded | Not recorded |
| Database observations | Not recorded | Not recorded | Not recorded |
Our recommendation is to choose the least aggressive candidate that passes every required criterion. If the baseline already meets the agreed need, keeping it is a valid outcome; tuning does not require accepting a change.
Sources: API load testing
How would a hypothetical comparison lead to acceptance and rollback?
The following worked example is hypothetical editorial guidance. Every workload, threshold and observation here is invented to demonstrate the decision process, not a measured result or a recommended target. Suppose a team compares two workers at effective concurrency 5 against the same two workers at 10, keeping the installed version, workflow revision, resource limits, database pool, payload mix, retries and dependency environment unchanged.
For each run, schedule one webhook request per iteration at two iterations per second for five minutes: 600 requests. Allow a further 60 seconds for recovery and reconcile every expected destination record. Before testing, set local criteria: all 600 results correct, no dropped iterations, HTTP response p95 below 500 milliseconds, dispatch-to-start p95 below two seconds, queue recovery within 60 seconds, peak worker memory below 75% of its limit, no API errors and no observed database blocking. The table shows fictional observations.
| Dimension | Baseline: 5 | Candidate: 10 |
|---|---|---|
| Delivered requests / dropped iterations | 600 / 0 | 600 / 0 |
| Correct destination results | 600 | 596 |
| HTTP response p95 | 300 ms | 280 ms |
| Dispatch-to-start p95 | 1.5 s | 0.8 s |
| Queue recovery | 30 s | 45 s |
| Peak worker memory / limit | 55% | 70% |
| API errors | 0 | 4 HTTP 429 responses |
| Database blocking observed | None | None |
| Decision | Pass | Fail |
Under these invented criteria, the baseline passes and the candidate fails despite its shorter dispatch-to-start delay. Retain the baseline. Before the candidate run, save its complete deployment revision as configuration A: two workers, --concurrency=5 and N8N_CONCURRENCY_PRODUCTION_LIMIT=-1, together with all unchanged settings. Candidate configuration B uses --concurrency=10 with that same environment value.
For this example, predeclare any HTTP 429 response as an immediate rollback trigger. When the first fictional 429 appears, stop arrivals and follow the planned shutdown procedure. Restore configuration A through the team's deployment mechanism, verify effective concurrency 5 on both workers, and reconcile uncertain writes. Replay the baseline workload; fictional recovery observations of 600 correct results, zero API errors and a 30-second queue recovery would satisfy these example recovery criteria. Preserve both the failed candidate record and the recovery evidence.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/scaling/control-concurrency.md at main · n8n-io/n8n-docs · GitHub, n8n/packages/cli/src/commands/worker.ts at master · n8n-io/n8n · GitHub, Enable queue mode | Deploy | n8n Docs
What makes a run pass, fail or inconclusive?
Separate correctness checks from test thresholds. Grafana notes that failed k6 checks do not fail or abort a test by default. Configure the intended pass/fail behavior explicitly.
As a suggested decision rule, pass only when delivered load, business correctness, latency, queue recovery, resources and dependency failures all satisfy the predeclared criteria. Fail when a valid comparison breaches a required criterion. Mark the result inconclusive when workloads differ, observations are insufficient or the generator misses the required schedule.
Keep stop conditions distinct from final acceptance. Suggested stop conditions include an agreed error boundary, unacceptable dependency impact or inability to observe the system adequately. Assign an operator who can act on those conditions while the run is underway.
Sources: Built-in metrics, API load testing
How do you roll back and confirm recovery?
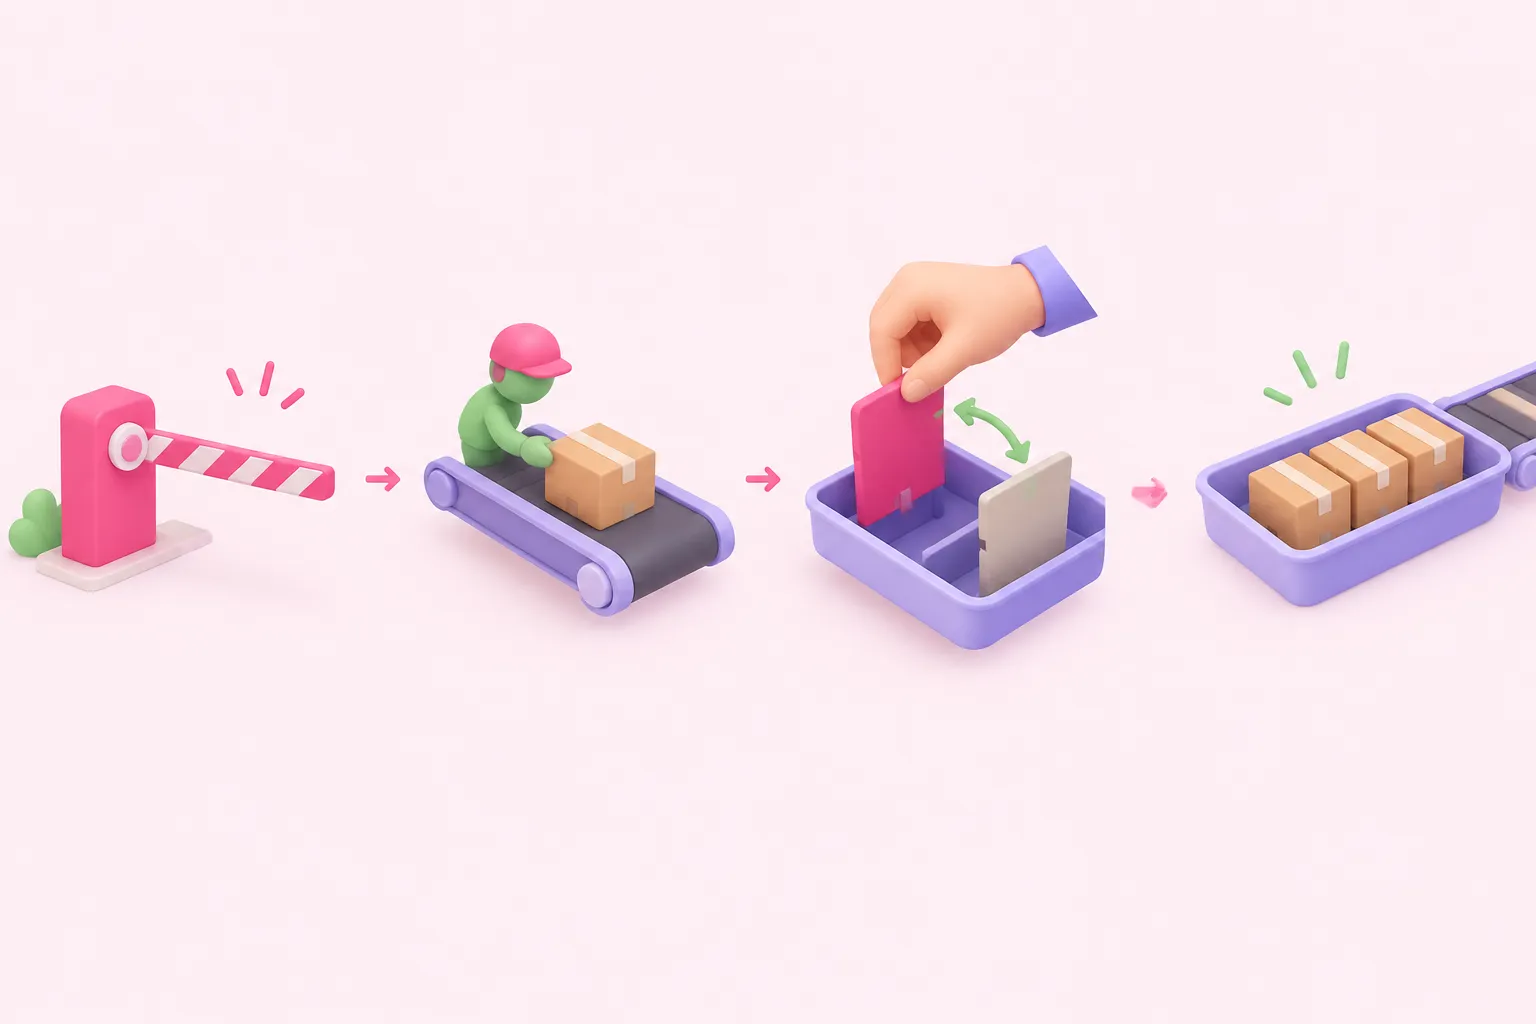
Restore the complete previous effective configuration, including any environment override, through your established deployment mechanism. n8n documents N8N_GRACEFUL_SHUTDOWN_TIMEOUT as the time allowed for executing worker jobs to finish before termination. Coordinate the surrounding shutdown allowance with that window.
Docker Compose documents stopping services without removing their containers and provides a shutdown timeout option. That stopping behavior is not a complete configuration-update procedure: starting an existing stopped container is not evidence that changed configuration has been applied.
A shutdown allowance does not guarantee that every execution finishes or that external writes happen exactly once. Include outcome reconciliation in your recovery plan. The sequence below is suggested editorial practice, to be adapted to your deployment.
- Stop test arrivals when a rollback trigger is reached.
- Use the planned shutdown procedure and observe executing work.
- Restore the preserved deployment revision and effective override.
- Verify each worker's applied configuration.
- Reconcile unfinished or uncertain business outcomes.
- Repeat the baseline workload and assess recovery criteria.
Sources: n8n-docs/docs/deploy/host-n8n/configure-n8n/scaling/control-concurrency.md at main · n8n-io/n8n-docs · GitHub, Enable queue mode | Deploy | n8n Docs, docker compose stop
What belongs in the final operating record?
Keep the accepted configuration, workload definition, delivered-load evidence, measurement coverage, acceptance decision, rollback trigger and recovery observations together. As a suggested handover practice, include the owner and the circumstances that should prompt another comparison, such as a changed workflow mix.
The result supports an operating choice for the tested workload and environment. Preserve enough detail for another operator to repeat the comparison and assess whether the decision still fits.